
What data for AI is
Put simply, it is anything you can record and count: pressure in a pipe, a receipt at the till, a patient scan, a customer email. A model learns from the history of such records and looks at fresh ones to spot a deviation or make a forecast.
Training data for AI must be past data with an outcome. Which readings came before a breakdown, which purchases came before a customer left? Without the outcome, the model sees numbers but does not understand what they mean.
Quality matters more than volume. A model repeats what it sees: if the history has gaps and errors, the forecast inherits them, and no algorithm can fix that.
Five sources of data
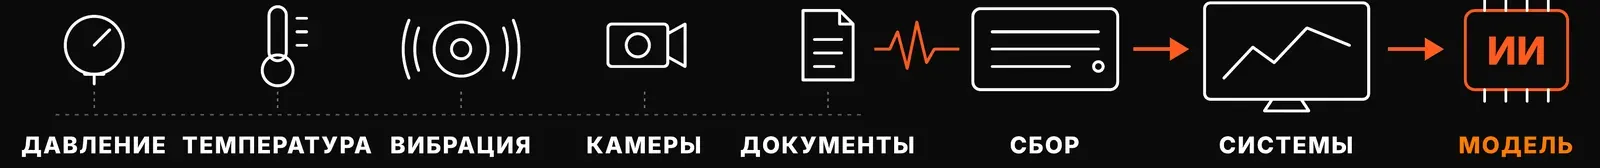
Almost everything a model needs comes from five sources: pressure, temperature, vibration, cameras and documents. Sensors and equipment give the first four, and accounting systems, contracts and correspondence give the fifth.
The path is always the same: source, collection, system, model. A sensor takes a reading, a collection device passes it to the accounting system or the control room, and from there the model takes an already cleaned picture.
A break at any step makes the rest worthless. A sensor whose readings go nowhere is useless, and so is a system where nobody enters records. The diagram below shows the whole chain.
How this path maps onto the four floors of a company is covered on the page about how AI works.
Resources and industry
In mining, companies measure pressure, flow and pump vibration, and the composition of the ore. The readings come from sensors, cameras on the conveyor, telemetry and satellites.
They go to the process control system, to SCADA, a supervisory control system, and to GIS, where the readings are tied to a map of the deposit.
In manufacturing, the main indicators are vibration, temperature, energy use and defects on the line. Vibration and temperature sensors, meters and cameras take the readings and pass them to SCADA, MES (a shop floor management system), ERP and the accounting system.
A typical problem in industry: the sensors are there, but the readings are kept only in the control room and get overwritten over time. For breakdown forecasts you need a long history together with a repair log, so the first step is often an archive.
Retail, finance and the public sector
In retail and finance, sales, stock, customer behavior and calls matter. Tills, the CRM, the call center and GPS trackers on vehicles collect them, and they are kept in the CRM, ERP, WMS (a warehouse management system) and BI, a reporting system for managers.
The main gap here is not in sensors but in links. Sales live at the till, stock in the warehouse system, requests in the call center, and until they are joined by customer and product, the forecast is built on half the picture.
In the public sector and healthcare, organizations measure citizen requests, scans, medical charts and queues. The sources are portals, an MIS (medical information system), cameras and document workflow, and everything is kept in the MIS, an EDMS (electronic document management system) and on government portals.
There is a lot of text and images here and few numbers. Language models and computer vision can handle them if records are kept electronically and in one format. Examples of solutions for public agencies are collected on the page about AI in public administration.
01 Resources
- What we measure
- pressure, flow, pump vibration, ore composition
- How we collect it
- sensors, conveyor cameras, telemetry, satellite
- Where we send it
- process control systems, SCADA, GIS
02 Industry
- What we measure
- vibration, temperature, energy, defects on the line
- How we collect it
- vibration and heat sensors, meters, cameras
- Where we send it
- SCADA, MES, ERP, 1C
03 Trade and finance
- What we measure
- sales, stock, customer behavior, calls
- How we collect it
- tills, CRM, call center, GPS trackers
- Where we send it
- CRM, ERP, WMS, BI
04 Public sector
- What we measure
- requests, scans, medical records, queues
- How we collect it
- portal, medical records system, cameras, document workflow
- Where we send it
- medical systems, document systems, state portals
How to tell whether you have enough data
Four questions show whether you have enough information. If the answer to all of them is “yes”, the solution can be costed. If not, a collection step appears in the map.
1. Is what you need recorded in a system, not in an employee’s head or a personal spreadsheet?
2. Is there a history for past periods, including the cases you need to predict: breakdowns, customer churn, spikes in demand?
3. Do the numbers match between systems: stock in the accounting system and in the warehouse, a customer in the CRM and in the books?
4. Who is responsible for each source, and can you get an export?
BCG estimates that about 70% of the difficulties in an AI rollout come from people and processes, 20% from technology and only 10% from algorithms. The questions above are exactly about people and processes: who records, who is responsible, who gives access.
How we check AI data readiness for each process is described on a separate page.
Data audit in AI Due Diligence
AI Due Diligence, a full review of a company before decisions about AI, includes an audit of information sources. For each process that may go into the map, we note where the records are, how complete they are and who has access.
The result for each process: “ready”, “needs cleaning” or “collect from scratch”. Collection from scratch gets its own cost and term in the map, as a separate solution.
This matters for the budget: 54% of organizations name high costs as a barrier, and 33% a lack of specialists (HSE ISSEK, September 2026). The audit shows which collection costs will pay off and which can wait.
You can start with a review: in 30 minutes, free of charge, we look at your systems and tell you which records are missing for the first solution.